AI Data Movement
TL;DR
• AI data movement is becoming a major challenge as AI workloads require faster data transfer.
• Memory bandwidth and high-speed networking are critical for AI performance.
• GPU-to-GPU communication can create bottlenecks in large AI systems.
• Efficient data movement can reduce latency, energy use, and infrastructure costs.
• Future AI infrastructure will need to optimize compute, memory, networking, and storage together.
Artificial intelligence is entering a phase where raw computing power is no longer the only factor determining performance. Modern AI systems depend on massive amounts of information moving between GPUs, memory, processors, storage, and networks. For businesses building intelligent applications, scalable AI software development solutions are increasingly connected to the infrastructure that moves and processes this data. As AI models become larger and workloads become more distributed, AI Data Movement is emerging as a critical infrastructure challenge that could influence speed, cost, efficiency, and scalability.
The AI industry has spent years focusing on faster processors. NVIDIA, AMD, custom AI chip developers, and semiconductor companies continue to increase accelerator performance. At the same time, however, the amount of data that these processors need to access and exchange is also increasing.
This creates an important question:
What happens when AI chips become faster than the infrastructure moving data between them?
The answer could define the next stage of AI infrastructure development.
What Is Data Movement in AI Infrastructure?
AI Data Movement refers to the transfer of information between the different components involved in an artificial intelligence workload.
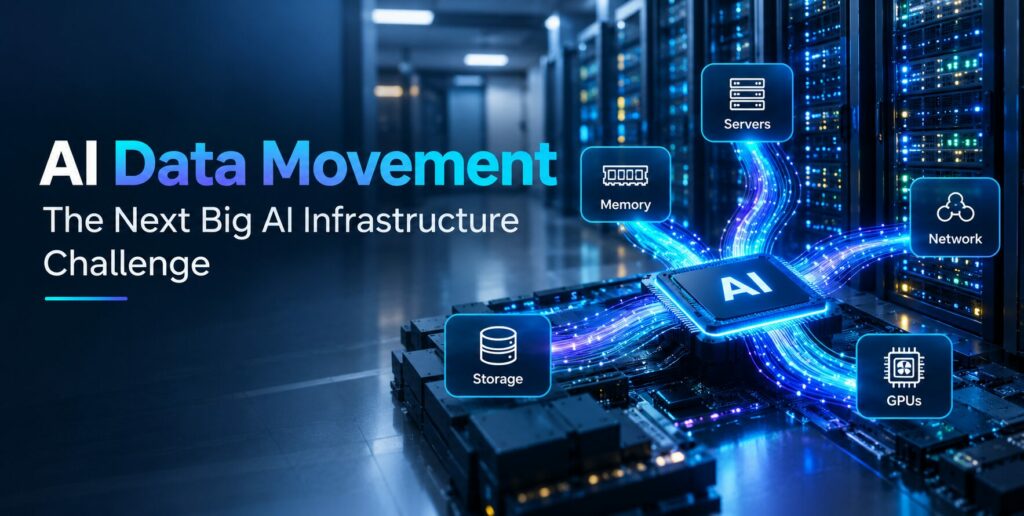
An AI application may move data between:
- GPUs and high-bandwidth memory
- GPUs and CPUs
- GPU-to-GPU systems
- Servers and network switches
- Storage and memory
- AI accelerators and custom chips
- Cloud infrastructure and applications
A large AI workload can involve millions or billions of data transfers during training or inference.
The problem is that data does not move instantly.
Every transfer can introduce latency, consume bandwidth, require energy, and place additional pressure on the infrastructure.
As AI workloads become more complex, inefficient data movement can prevent expensive computing resources from being used efficiently.
Why Faster AI Chips Are Not Enough
AI accelerator performance has improved rapidly.
Modern GPUs and specialized AI processors can perform enormous numbers of calculations per second. But a processor cannot work efficiently if the data it needs is not available quickly enough.
Imagine a manufacturing facility with extremely fast machines but a slow conveyor belt. The machines may have impressive capabilities, but production can still be limited because materials cannot reach them quickly enough.
AI infrastructure can face a similar problem.
A GPU may be capable of processing data at extremely high speeds, but if memory, networking, or storage cannot supply that data quickly enough, part of the available computing capacity may remain underutilized.
This is why the future of AI infrastructure is increasingly about balancing compute with communication.
The Growing Data Transfer Challenge
AI models are becoming larger, while AI applications are also becoming more sophisticated.
Large language models, multimodal AI systems, recommendation engines, computer vision platforms, and AI agents can require enormous amounts of data.
During model training, multiple accelerators may need to exchange parameters, gradients, and intermediate information.
During inference, the system may need to access model weights, contextual information, memory caches, user data, and external knowledge.
AI agents can create an even more complicated pattern.
An agent may receive a request, retrieve information from a database, call an API, access a knowledge base, execute a tool, process the result, and then generate an answer.
Each step can create additional data transfers.
As a result, AI data center infrastructure needs to handle not only more computation but also increasingly complex communication patterns.
Why Memory Matters for AI Performance
Memory plays a major role in AI performance.
Large AI models require substantial memory capacity and high memory bandwidth. Technologies such as High Bandwidth Memory, commonly known as HBM, have become increasingly important for AI accelerators.
However, increasing memory bandwidth does not completely solve the problem.
Data still needs to move between different memory levels, processors, accelerators, and storage systems.
This makes memory architecture an important part of AI data movement optimization.
The relationship between compute and memory is particularly important for inference workloads.
When an AI system handles a large number of simultaneous requests, memory bandwidth and capacity can influence how efficiently the model responds.
For applications where users expect near-real-time responses, unnecessary data transfers can contribute to increased latency.
Networking Is Becoming Part of AI Computing
Networking was traditionally viewed as the infrastructure connecting servers and applications.
AI is changing that relationship.
Large AI clusters can contain many accelerators that need to communicate with each other. The network connecting these accelerators can therefore influence overall system performance.
This has led to growing investment in high-speed AI networking and specialized interconnect technologies.
Modern AI infrastructure increasingly uses technologies designed to provide faster communication between GPUs and other accelerators.
The objective is straightforward:
Move more data, with less delay, while using infrastructure efficiently.
This is particularly important for distributed AI training, where multiple processors work together on the same model.
If communication between those processors becomes inefficient, additional computing power may not translate into proportional performance improvements.
Scale-Up vs. Scale-Out AI Infrastructure
Understanding AI networking infrastructure requires looking at two different forms of scaling.
Scale-Up
Scale-up means connecting processors within a tightly integrated system.
For example, multiple GPUs may communicate through a high-speed interconnect so they can operate as a coordinated computing environment.
The objective is to reduce communication delays and provide extremely high bandwidth.
Scale-Out
Scale-out involves connecting multiple servers, systems, or racks.
When an AI workload becomes too large for one server, it can be distributed across a much larger cluster.
This introduces additional challenges.
The infrastructure needs to manage:
- Network congestion
- Latency
- Bandwidth
- Data synchronization
- Load balancing
- Fault tolerance
- Efficient workload placement
As AI clusters become larger, scale-out networking can become just as important as the processors themselves.
AI Inference Could Make Data Movement More Important
Training receives much of the attention in AI infrastructure discussions, but inference is becoming increasingly significant.
Inference is the process of using a trained AI model to generate predictions, responses, classifications, or other outputs.
Every AI interaction requires data to move through a system.
A simplified process could look like:
User → Application → Network → AI Model → Memory → Accelerator → Network → Application → User
Real-world architectures can be significantly more complex.
For example, an enterprise AI assistant might need to retrieve information from company databases before generating an answer.
That means the system is not simply running a model.
It is moving information between applications, databases, memory, networking systems, and AI accelerators.
This makes AI inference optimization a broader infrastructure challenge.
AI Agents Increase the Complexity
The rise of AI agents introduces another dimension to data movement.
Traditional generative AI applications generally follow a relatively straightforward interaction:
Prompt → Model → Response
An AI agent can involve multiple steps:
Request → Reasoning → Data Retrieval → Tool Use → Processing → Verification → Action
Every additional step may involve communication between different services.
An enterprise agent could interact with a CRM, database, cloud service, document repository, search engine, or external API.
This means agentic AI infrastructure must be designed to efficiently move information between multiple systems.
As AI agents become more capable, data movement between AI systems could become an increasingly important consideration for developers and infrastructure teams.
Storage Can Become Another Bottleneck
AI systems do not only depend on GPUs and memory.
They also need access to enormous amounts of data.
Training datasets, documents, images, videos, model checkpoints, embeddings, logs, and application data can all reside in storage systems.
If data must travel through multiple layers before reaching an accelerator, additional latency and processing overhead can occur.
This is why AI infrastructure designers are exploring architectures that reduce unnecessary data copies and create more direct paths between storage and compute.
The goal is to bring the data closer to where it is being processed.
This concept of data locality in AI can become increasingly important as workloads grow.
Custom AI Chips Are Also Changing Data Movement
The AI hardware ecosystem is becoming more diverse.
While GPUs remain central to many AI systems, companies are also developing custom accelerators for specific workloads.
Some processors are designed specifically for inference. Others target recommendation systems, machine learning, edge AI, or specialized enterprise applications.
Recent industry activity also shows growing attention toward technologies that connect custom AI processors with larger AI infrastructure systems. Reuters reported in September 2026 that inference-chip company d-Matrix plans to use NVIDIA’s NVLink Fusion technology to connect its processors within AI server infrastructure.
This demonstrates an important point.
A custom AI chip is only one part of the solution.
Its ability to communicate efficiently with memory, GPUs, networking components, and other processors is equally important.
Data Transfer and Energy Efficiency
Data movement is not only a performance issue.
It can also affect energy consumption.
Moving data between chips, memory, and servers requires energy. As AI data centers become larger, the energy associated with communication can become an important part of overall infrastructure efficiency.
This means AI efficiency should not be measured only by how many calculations a processor can perform.
Businesses may increasingly need to consider:
- Performance per watt
- Data transfer efficiency
- Memory utilization
- Network efficiency
- Accelerator utilization
- Storage efficiency
- Latency per request
The broader objective is to get more useful AI work from every unit of computing and energy.
The Economics of AI Infrastructure
AI infrastructure is expensive.
Companies investing in AI need to consider the total cost of operating large computing environments.
If accelerators are expensive but spend significant time waiting for data, organizations may not receive the full value of their hardware investment.
This makes AI infrastructure efficiency an economic issue as well as a technical one.
Better data movement can potentially help organizations improve:
- GPU utilization
- Response times
- Infrastructure capacity
- Energy efficiency
- Cost per inference
- Overall AI application performance
Recent investment activity reflects the growing importance of this problem. For example, Reuters reported on September 15, 2026, that Delos Data raised $100 million to develop chips and software focused on improving data movement in increasingly complex AI data centers.
The development highlights how data communication is becoming a distinct area of AI infrastructure innovation.
How Businesses Can Prepare
Businesses planning AI deployments should look beyond model selection.
A complete AI infrastructure strategy should consider the entire data path.
1. Evaluate Data Requirements
Understand what information the AI system needs and where that information is stored.
2. Reduce Unnecessary Data Transfers
Where possible, move computation closer to the data rather than repeatedly transferring large datasets.
3. Optimize Memory Usage
Evaluate memory capacity, bandwidth, caching, and data access patterns.
4. Plan Networking Early
Networking should be considered part of the AI architecture rather than an afterthought.
5. Monitor AI Workloads
Track latency, bandwidth utilization, accelerator utilization, and infrastructure costs.
6. Design for Future Scale
An architecture that works for a small AI application may not work when usage increases dramatically.
Scalability should therefore be considered from the beginning.
What the Future of AI Infrastructure Could Look Like
The future of AI infrastructure is likely to involve tighter integration between compute, memory, networking, and storage.
Instead of treating these components as separate layers, infrastructure designers may increasingly optimize them as one connected system.
This could lead to:
- Faster accelerator interconnects
- More advanced memory architectures
- Intelligent networking
- Specialized AI networking chips
- More efficient storage-to-GPU communication
- Improved data locality
- Advanced chip-to-chip communication
- Software optimized for distributed AI workloads
The goal will not simply be to build faster processors.
It will be to ensure that every component can communicate efficiently with the others.
For AI application developers, this evolution will also influence how applications are designed. Understanding infrastructure, data pipelines, model architecture, and application requirements together will become increasingly important.
You can follow more developments across AI infrastructure, enterprise AI, and emerging technology through AI technology trends and industry insights.
Conclusion
AI Data Movement is becoming one of the most important challenges in the evolution of AI infrastructure.
The industry has made enormous progress in AI compute, but faster processors create new demands on memory, networking, storage, and communication systems.
As models become larger and AI applications become more distributed, the ability to move information efficiently could have a direct impact on performance, latency, energy use, and cost.
The next generation of AI data centers will therefore need to think beyond GPUs.
Compute matters. Memory matters. Networking matters. Storage matters. But the connections between them may matter just as much.
The future of AI infrastructure may ultimately depend not only on how quickly machines can calculate, but on how efficiently they can move the data required to calculate.
Frequently Asked Questions
1. What is AI data movement?
AI data movement is the transfer of data between GPUs, memory, servers, networking systems, and storage during AI workloads.
Why is data movement important for AI infrastructure?
Efficient data transfer helps reduce bottlenecks, latency, energy consumption, and infrastructure costs while improving AI workload performance.
How does memory bandwidth affect AI performance?
Higher memory bandwidth allows AI accelerators to access data faster, helping prevent compute resources from waiting for data.
Can networking become a bottleneck for AI systems?
Yes. As AI workloads scale across multiple GPUs and servers, slow or inefficient networking can limit overall system performance.
Why is data movement important for AI inference?
Inference often requires frequent movement of model data and user inputs between compute, memory, and other infrastructure components, making efficient transfers important for low latency.
How can businesses improve AI data movement efficiency?
Businesses can optimize memory usage, reduce unnecessary transfers, use high-speed networking, and design infrastructure around the needs of specific AI workloads.