AI Memory Bottleneck
TL;DR
• AI memory is becoming a major AI infrastructure challenge.
• HBM and memory bandwidth are key to AI performance.
• Larger models require more memory and faster data access.
• Faster GPUs alone cannot remove memory bottlenecks.
• Future AI systems will optimize compute, memory, and data movement together.
Artificial intelligence has traditionally been associated with powerful GPUs and increasingly capable processors. But as AI models become larger, context windows grow longer, and inference workloads become more demanding, another part of the system is becoming just as important: memory. Businesses developing scalable AI software solutions increasingly need to consider not only how much computing power they have, but also how quickly data can be stored, accessed, and delivered to that compute.
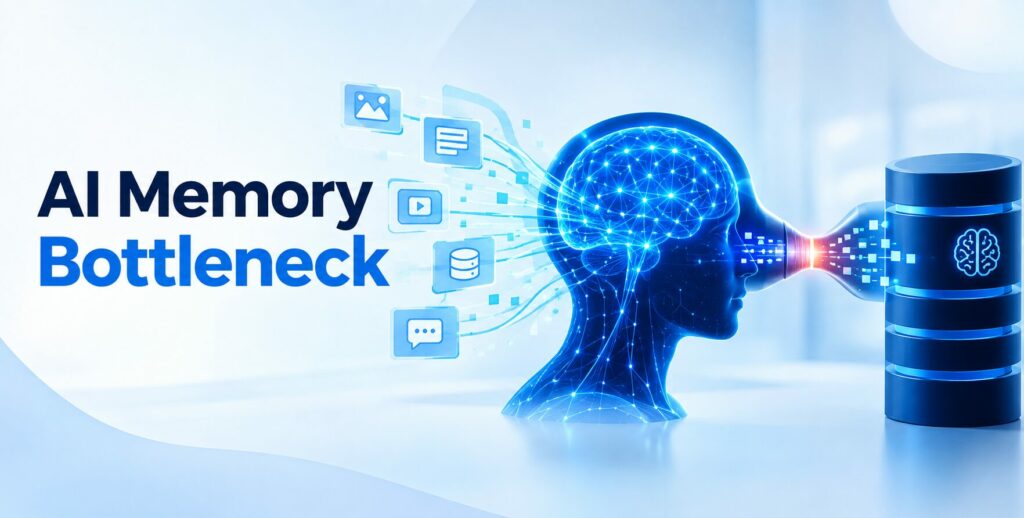
This shift is changing the way modern AI infrastructure is designed. Faster processors can perform enormous numbers of calculations, but they still depend on memory to supply the data required for those calculations. If memory capacity or bandwidth cannot keep up, expensive compute resources may spend more time waiting for data than processing it.
Recent industry research reinforces this change. Gartner said in May 2026 that the AI infrastructure bottleneck had shifted from accelerator silicon toward the memory and back-end stack, including high-bandwidth memory (HBM) and advanced packaging. Gartner also forecasts memory revenue of $837 billion in 2026, with AI infrastructure driving strong demand for memory products.
For more coverage of emerging AI infrastructure developments, AI technology trends and infrastructure insights provide useful context around how the AI computing stack is evolving.
Why Compute Alone Is Not Enough
AI performance is often discussed in terms of GPU speed, accelerator performance, or the number of operations a processor can perform per second. These measurements are important, but they do not tell the entire story.
An AI accelerator needs continuous access to data. Model weights, activations, intermediate results, prompts, and other information must move between different layers of the memory hierarchy.
If the processor can calculate faster than the memory system can supply data, the additional compute capacity may not translate directly into better application performance.
This creates a fundamental relationship:
More compute power requires enough memory capacity and bandwidth to keep that compute busy.
That is why the conversation around AI infrastructure is expanding from GPUs to the complete system, including memory, networking, storage, packaging, and data movement.
What Is the AI Memory Bottleneck?
The AI Memory Bottleneck occurs when memory capacity, bandwidth, latency, or data movement limits the performance of an AI workload.
There are several ways this can happen.
Memory capacity determines how much data can remain available close to the processor.
Memory bandwidth determines how quickly that data can be transferred.
Memory latency affects how long the system must wait before accessing required information.
Data movement determines how efficiently information travels between compute and memory.
A system can have an extremely powerful GPU and still experience performance limitations if one of these areas becomes a constraint.
This is especially important for large language models and other AI systems that process enormous amounts of data during training and inference.
HBM Is Becoming Critical to AI Performance
High-bandwidth memory, commonly known as HBM, has become one of the most important technologies in modern AI computing.
Unlike conventional memory architectures, HBM uses stacked memory dies and a wide interface to provide very high bandwidth close to AI accelerators.
Modern HBM generations are being developed specifically for increasingly demanding AI workloads. Micron says its HBM4 technology can provide more than 2.8 TB/s of bandwidth per stack, while HBM3E provides more than 1.2 TB/s per stack.
The importance of this bandwidth becomes clearer when considering how AI models operate.
A processor may need to repeatedly access large amounts of model data. If that information cannot reach the compute units quickly enough, processor utilization can suffer.
HBM therefore does not simply provide more memory. It provides a high-speed path for supplying data to the accelerator.
Memory Bandwidth Can Become the Real Performance Limit
Memory capacity and memory bandwidth solve different problems.
A system may have enough memory to store a model but still struggle to deliver the data quickly enough.
This is where memory bandwidth becomes critical.
Consider a large AI workload running on a powerful accelerator. The processor may be capable of handling enormous computational workloads, but it needs a continuous stream of model data and intermediate information.
If the memory subsystem cannot deliver that data quickly enough, the accelerator may not operate at its full potential.
Micron describes memory bandwidth as a major constraint for large language model inference and notes that different query types can produce substantially different bandwidth requirements.
This means infrastructure designers increasingly need to consider the characteristics of the workload rather than simply choosing the fastest available processor.
Larger Models Are Increasing Memory Requirements
AI models have grown dramatically in size and complexity.
Larger models generally require more memory to store their parameters and supporting data. But model size is only part of the story.
Modern AI applications can also maintain:
- Long conversation histories
- Large context windows
- Retrieval information
- Tool outputs
- Intermediate reasoning states
- Key-value caches
- Multimodal data
- Agent memory
As these requirements grow, memory capacity becomes increasingly important.
Micron reported in 2026 that AI context lengths were increasing rapidly while memory content per server had also grown significantly, reinforcing the growing importance of memory bandwidth and capacity.
The result is a new infrastructure challenge: AI systems need both more memory and faster access to that memory.
Long Context Windows Are Changing the Memory Equation
Long-context AI is another reason memory requirements are increasing.
A model that processes a short prompt has different memory requirements from a system that works with hundreds of thousands or millions of tokens.
Longer contexts can require larger key-value caches and more memory resources during inference.
This becomes particularly important for applications involving:
- Large documents
- Software repositories
- Enterprise knowledge bases
- Research databases
- Long conversations
- Multimodal information
- Autonomous AI workflows
Micron’s HBM4 materials specifically highlight ultra-long context windows and real-time multimodal AI workloads as use cases driving the need for higher bandwidth.
As context grows, memory architecture becomes increasingly important to maintaining acceptable performance.
AI Inference Is Increasing Memory Pressure
Training gets significant attention because it requires enormous computing resources. However, inference introduces a different challenge because models need to serve users continuously.
A popular AI application may process millions of requests over time.
Each request consumes computing and memory resources. In some workloads, the limiting factor may not be raw arithmetic performance but the speed at which model data can be accessed and moved.
This is one reason memory optimization is becoming central to AI inference performance.
Efficient memory systems can help:
- Keep frequently accessed data closer to compute
- Reduce unnecessary data movement
- Improve accelerator utilization
- Support larger workloads
- Reduce latency
- Improve performance per watt
Micron’s analysis of AI infrastructure similarly emphasizes memory and storage as foundational parts of training and inference systems.
Agentic AI Could Make Memory Demands Even Higher
The rise of agentic AI adds another layer of complexity.
Traditional AI applications may generate a response from a single request. AI agents can perform multiple steps, interact with tools, maintain context, and work through longer workflows.
An agent may need to keep track of:
- The original user request
- Previous actions
- Tool results
- Retrieved information
- Intermediate states
- Previous conversations
- Current task objectives
That information needs to be accessed efficiently.
Micron research on agentic AI identifies memory resources as increasingly important for high-throughput and low-latency agent workflows.
As autonomous systems become more sophisticated, memory architecture could become an important factor in how quickly and efficiently agents can operate.
Memory and Data Movement Are Closely Connected
Memory cannot be considered separately from data movement.
AI systems constantly move information between processors, HBM, system memory, storage, and networking components.
This means a memory bottleneck can sometimes be part of a broader AI data movement problem.
For example, if data needs to travel repeatedly between different components, the system can experience latency and bandwidth limitations even when individual components are extremely fast.
This is why AI infrastructure increasingly needs to be designed as a complete system rather than as a collection of independent hardware components.
Our article on AI data movement and infrastructure bottlenecks explores this connected challenge in greater detail.
Memory Shortages Are Also Affecting the AI Hardware Market
The importance of memory is not limited to technical performance.
AI infrastructure demand is also affecting the memory supply chain.
Gartner forecasts that worldwide memory revenue will reach $837 billion in 2026, up sharply from 2025, and expects memory to account for 54% of total semiconductor revenue in 2026. Gartner also says AI infrastructure deployments are increasing memory consumption and sustaining demand for HBM.
Gartner separately reported that shortages and longer lead times for DRAM and HBM were creating challenges for technology buyers during 2026.
This means memory is becoming both a performance issue and a supply-chain issue.
For organizations planning large AI deployments, the availability, price, and type of memory can influence infrastructure decisions.
Why Faster GPUs May Not Solve the Problem
It is tempting to assume that buying newer and faster GPUs will automatically improve AI performance.
But the relationship between compute and memory is more complicated.
Imagine upgrading an AI server with a much faster accelerator while leaving the rest of the system unchanged. If memory bandwidth cannot increase accordingly, the accelerator may not be fully utilized.
The same principle applies to networking and storage.
A high-performance AI system needs balance across multiple layers:
Compute → Memory → Networking → Storage → Software
If one layer becomes significantly slower than the others, it can limit the overall system.
This is why modern AI infrastructure increasingly focuses on system-level optimization rather than isolated component performance.
The Future of AI Hardware May Become Memory-Centric
For years, the AI hardware conversation was dominated by processor performance.
That is changing.
Gartner’s 2026 analysis says the infrastructure bottleneck has moved toward HBM and the broader memory and back-end stack rather than being concentrated solely around accelerators.
At the same time, Gartner expects demand to broaden across networking, storage, power, optical components, and other parts of the AI infrastructure stack.
This suggests that future AI systems will increasingly be designed around the relationship between compute and memory.
Instead of asking only:
“How powerful is the GPU?”
Organizations may increasingly ask:
“Can the entire system keep the GPU supplied with data?”
That is a fundamentally different way of evaluating AI infrastructure.
How Businesses Can Prepare
Businesses planning AI deployments can take several steps to reduce memory-related bottlenecks.
Evaluate Memory Requirements Early
Memory should be considered during AI architecture planning rather than after hardware has already been selected.
Teams should estimate model size, context requirements, concurrent users, and expected inference workloads.
Match Memory to the Workload
Different AI applications have different requirements.
Some may prioritize bandwidth, while others need higher capacity or lower latency.
Understanding the workload helps organizations choose appropriate memory technologies.
Optimize Models
Model optimization techniques such as quantization, pruning, and distillation can reduce memory requirements in appropriate use cases.
Smaller models can also make deployment easier for edge and enterprise environments.
Reduce Unnecessary Data Movement
Moving data repeatedly between memory layers can create additional latency and energy costs.
Efficient software and system architecture can reduce unnecessary transfers.
Consider the Complete Infrastructure
Memory should be evaluated alongside:
- GPUs and AI accelerators
- Networking
- Storage
- Cooling
- Power
- Software
- Data pipelines
Optimizing one component while ignoring the rest can leave other bottlenecks unresolved.
What the AI Memory Shift Means for the Industry
The growing importance of memory could influence the AI industry in several ways.
First, memory manufacturers and HBM suppliers are becoming increasingly important to AI infrastructure.
Second, chip designers may need to develop processors and memory systems together rather than treating them as separate components.
Third, cloud providers may increasingly differentiate their AI infrastructure through memory capacity, bandwidth, and architecture.
Finally, software developers will have greater incentives to build models and applications that use memory efficiently.
The result could be a broader shift from compute-first AI design toward balanced system design.
Conclusion
The AI Memory Bottleneck is becoming an important issue because AI performance is no longer determined by compute power alone.
Faster GPUs can deliver impressive computational performance, but they still depend on memory to provide the data they need. As models become larger, context windows expand, inference workloads increase, and AI agents perform longer workflows, memory capacity and bandwidth become increasingly important.
HBM is emerging as a critical technology for keeping AI accelerators supplied with data, while broader memory and storage architectures are becoming central to AI infrastructure design. Gartner’s latest forecasts also show how strongly AI is reshaping memory demand and the semiconductor market.
The next phase of AI development will therefore involve more than building faster processors. It will require a balanced infrastructure stack where compute, memory, networking, storage, and data movement work together efficiently.
In other words, the future of AI may not simply belong to the systems with the most compute. It may increasingly belong to the systems that can move, store, and access data efficiently enough to keep that compute working.
Frequently Asked Questions
What is an AI memory bottleneck?
It occurs when AI systems cannot access data fast enough for the processor.
Why is memory important for AI?
Fast memory helps GPUs process data efficiently and reduces delays.
What is HBM in AI?
HBM is high-bandwidth memory designed to deliver data quickly to AI processors.
Can faster GPUs solve memory bottlenecks?
Not always. Performance can still be limited by memory bandwidth and data movement.
Why do AI models need more memory?
Larger models and longer contexts require more space for weights and KV cache.
How can AI memory bottlenecks be reduced?
Techniques include HBM, quantization, caching, and better data movement.